Loading...

SQLAlchemy Hacks: Go Beyond Basic with Custom Data Types for Epic Models

SQLAlchemy Hacks: Go Beyond Basic with Custom Data Types for Epic Models

Shakir Khan

21 November 2025

backend automation AI DevOps

Ever feel like your SQLAlchemy models are a bit… vanilla? Like they’re doing the job, but not really *singing*? Well, buckle up, because we’re about to dive into some serious SQLAlchemy hacks that will let you go beyond basic and craft truly epic models using the magic of custom data types. Forget those boring integers and strings for a moment; it’s time to supercharge your database interactions!

Why Even Bother with Custom Data Types?

You might be thinking, “My `String` and `Integer` types work just fine, thanks!” And you’re right, they do – for most basic scenarios. But what happens when you need to store something a bit more complex? Maybe a specific UUID format, an encrypted field, or a custom object that needs special serialization and deserialization? This is where custom data types become your best friend. They allow you to define exactly how your Python objects interact with the underlying database columns, bringing a whole new level of power to your SQLAlchemy models.

Your First Step to Epic Models: The TypeDecorator

The secret sauce for most SQLAlchemy custom data types is the `TypeDecorator`. It’s like a wrapper around an existing SQLAlchemy type, allowing you to intercept values both when they go into the database and when they come out. Let’s imagine you always want to store a specific kind of serialized JSON object, but in your Python code, you want to work with a regular dictionary. Here’s a peek at how you’d start implementing this SQLAlchemy hack:

from sqlalchemy.types import TypeDecorator, Text
import json
class JsonEncodedDict(TypeDecorator):
    """Enables Python dicts to be stored as JSON in the database."""
    impl = Text # Use TEXT for storing JSON strings
    def process_bind_param(self, value, dialect):
        if value is not None:
            return json.dumps(value)
        return value
    def process_result_value(self, value, dialect):
        if value is not None:
            return json.loads(value)
        return value


With `JsonEncodedDict`, you can now define a column in your model like `data = Column(JsonEncodedDict)` and SQLAlchemy will automatically handle the `json.dumps` and `json.loads` for you. How cool is that for a simple SQLAlchemy hack to go beyond basic types?

Beyond JSON: Unleash More Creativity!

The `TypeDecorator` isn’t limited to JSON. Think about what else you could do: storing encrypted strings, custom UUID objects that always return `uuid.UUID` instances, specialized date formats, or even integrating with external libraries that have their own object types. These custom data types are the building blocks for truly resilient and expressive epic models. They clean up your application code by moving data conversion logic into the ORM layer, making your models smarter and your code drier.

Tips for Mastering Your Custom Data Types

  • Keep it Focused: Each custom type should ideally handle one specific transformation or validation.
  • Test Thoroughly: Make sure your `process_bind_param` and `process_result_value` functions handle `None` values and edge cases correctly.
  • Documentation is Key: Future you (and your teammates) will thank you for clear docstrings explaining what your custom type does.
  • Consider Performance: For very large data sets, complex serialization/deserialization can add overhead. Profile if necessary!

Go Forth and Create Epic Models!

So there you have it! Don’t let standard data types limit your imagination. With these SQLAlchemy hacks, specifically `TypeDecorator` and the power of custom data types, you’re now equipped to go beyond basic CRUD operations and build incredibly powerful, expressive, and truly epic models that perfectly fit your application’s unique needs. Start experimenting, and watch your SQLAlchemy game level up!

RECENT POSTS

Reducing Loan Processing Time Through Workflow Automation: What Actually Works

If you’ve spent any time in lending operations, you already know the real cost of a slow loan cycle isn’t just customer frustration — it’s lost business. A borrower who waits 10 days for approval has usually applied with two other lenders in the meantime. We’ve seen this play out repeatedly with our BFSI clients […]
How to Plan a Phased ERP or CRM Implementation Without Breaking What Already Works

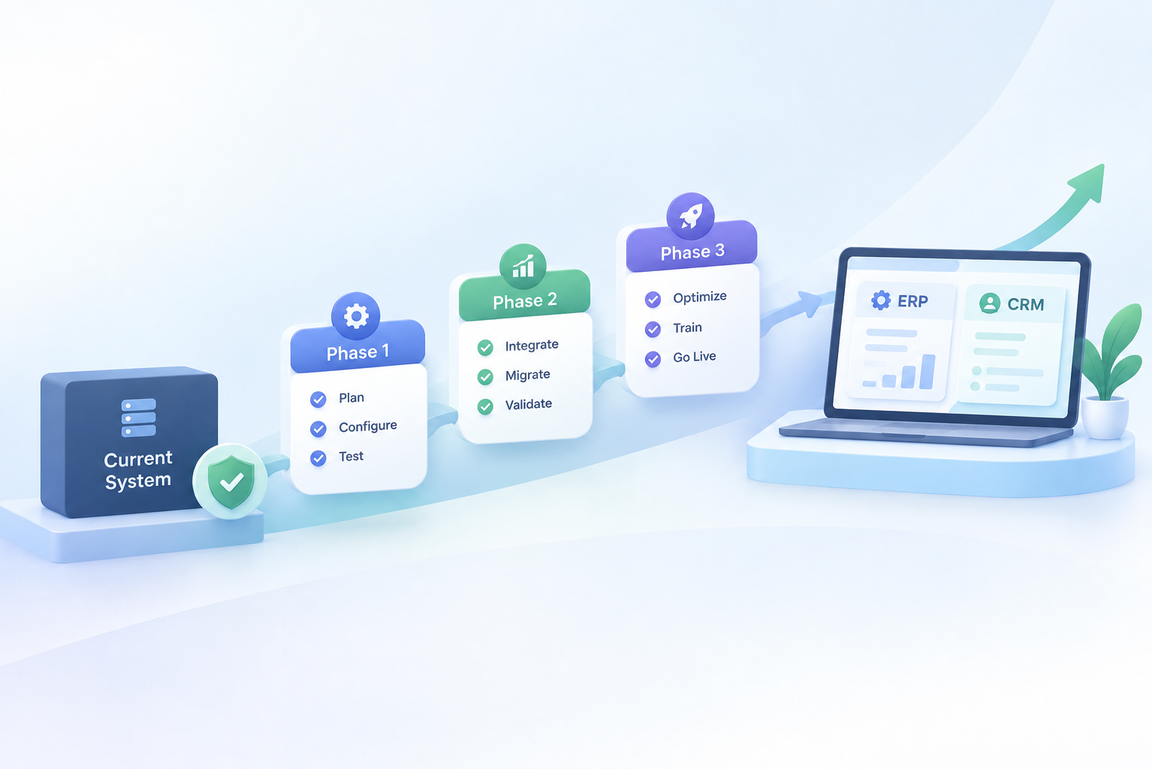
Every BFSI or fintech leader we’ve worked with has heard the same horror story at least once — a bank or NBFC switches on a new core system overnight, and for three weeks nobody can process loan disbursements properly. That’s the risk of a “big-bang” ERP or CRM rollout, and it’s exactly why phased implementation […]

Why Microservices Architecture Reduces Long-Term Maintenance Cost (A BFSI Perspective)

Every BFSI and fintech leader we’ve worked with at Speqto Technologies eventually asks us the same question: “Our monolith works fine today, so why should we spend money breaking it apart?” Fair question. The honest answer is — you shouldn’t do it for today. You do it for the three years after today, when your […]

Building Customer-Facing Portals for Financial Institutions: What Actually Works

Over the last few years, our team at Speqto Technologies has built portals for NBFCs, cooperative banks, insurance brokers, and a couple of wealth management firms. One thing that keeps surprising clients: the hardest part is rarely the UI. It’s getting core banking integrations, compliance workflows, and support escalation to work together without the whole […]

How AI Can Improve Fraud Detection in Banking Systems: What Actually Works

Most banks we talk to aren’t short on fraud rules. They have hundreds of them — thresholds on transaction amount, geography mismatches, velocity checks, blacklisted IFSC codes. The problem isn’t the lack of rules; it’s that fraudsters have learned to operate just below every threshold. That’s where AI earns its place, not as a buzzword, […]

POPULAR TAG

POPULAR CATEGORIES